blog
July 30, 2026
MobiSys 2026: Physical Intelligence and the Future of Embodied Systems
Our favorite papers from ACM Mobisys 2026 at the Universtiy of Cambridge

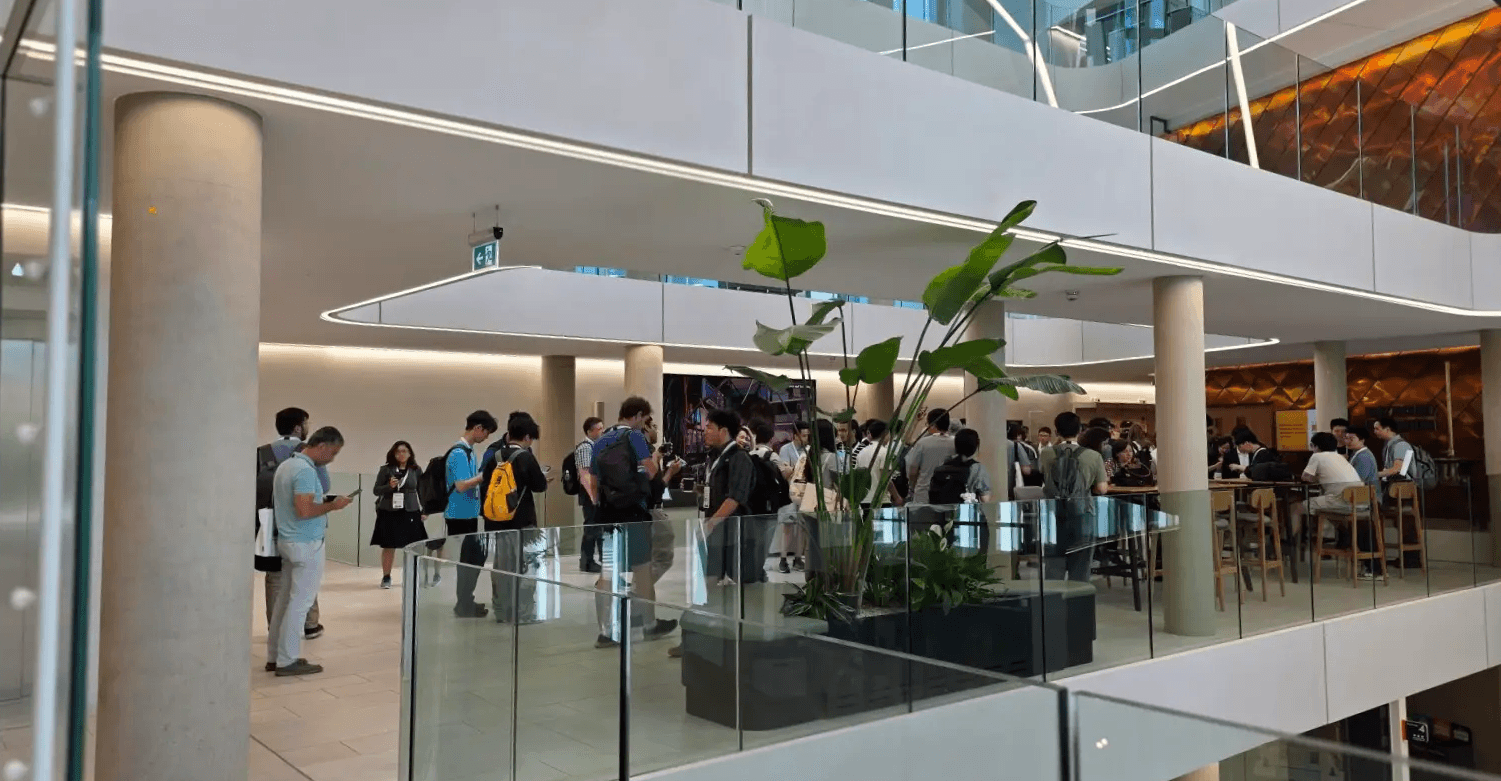
Analog Devices, Inc. (ADI) was proud to sponsor ACM MobiSys 2026, held at the University of Cambridge, one of the premier events for mobile systems, edge computing, and emerging physical AI research. Beyond the technical sessions, one of the highlights of the event was the opportunity to engage with researchers, students, and industry leaders working at the intersection of AI and the physical world.
The conversations throughout the conference reinforced a trend we have been observing: the next generation of intelligent systems will not be defined solely by larger models, but by how effectively sensing, computation, communication, and real-world action are integrated into a unified system. While the conference covered a broad range of topics, several presentations stood out for their relevance to ADI's interests in intelligent sensing, edge AI, robotics, and physical intelligence. These were our favorite talks from the event.
TimelyLLM: Time-sensitive LLM Serving System for Physical-I/O Limited Agents
Paper: https://arxiv.org/pdf/2412.18695
The talk, a best paper runner-up presented by a Yale University team, addressed the challenge of serving embodied agents like robots and drones with LLMs. Models must produce not only correct results but also arrive within time constraints. Existing engines such as vLLM batch requests first-come, first-served, so an urgent "avoid collision" command needing 200 ms can stall behind a non-urgent "find the hammer" request. The presenters’ key idea builds on the observation that for physical agents, execution is slower than generation: TimelyLLM, which is LLM-agnostic, partitions plan generation into executable segments and reallocates GPU resources to urgent requests, cutting waiting time by up to 84%. The approach reframes serving around real-time deadlines rather than throughput, a dimension we should account for when studying inference for embodied agents. The paper also offers a clean serving-layer baseline to build on without retraining models.
Artificial Tripartite Intelligence: A Bio-Inspired, Sensor-First Architecture for Physical AI
Paper: https://arxiv.org/pdf/2604.13959
The other best paper runner-up was presented by a team from Seoul National University and reframed perception for physical AI around the observation that systems often fail before inference: deployment changes what image sensors capture through motion blur, lighting, or occlusion. Such degraded input makes predictions unreliable regardless of model quality. The authors suggest a shift in where intelligence sits rather than pushing every hard case onto an ever larger neural network. Their solution relies on a bio-inspired architecture composed of three layers: a reflex layer that maintains safe operation, a calibration layer that continuously adjusts sensor parameters such as exposure and ISO, and an inference layer that processes the resulting data.
Tags
Comments
Join the conversation at EngineerZone
Opinions expressed in the content posted here are the personal opinions of the original authors, and do not necessarily reflect those of Analog Devices, Inc (ADI) or its subsidiaries. The content is provided for informational purposes only and is not meant to be an endorsement or representation by ADI or any other party. This site may also provide links or references to non-ADI sites and resources. ADI makes no representations, warranties, or other commitments whatsoever about any non-ADI sites or third-party resources that may be referenced, accessible from, or linked to this site.